GPTBot checker: can AI bots actually reach your site?
Say what you want from AI bots. Test a URL against it, see where your site differs, and copy the robots.txt that closes the gap.
How the GPTBot checker tests each bot
Each bot gets two checks. First, the checker reads your robots.txt the way that bot would and shows the line that decides. Second, it requests your URL with the bot's user agent and records the status code and whether a challenge page came back. The 16 bots with a live fetch run one after another and count as one check. 25 more bots, mostly control tokens and minor crawlers, get the robots.txt check only.
The fetch comes from Firemark's servers, outside the bots' own IP ranges. A firewall that verifies bots by IP can treat the real bot differently, so read a 403 here as a strong signal and let your firewall log settle it. Results are kept for 24 hours, with the time shown.
Search, user-triggered and training bots
Search bots
Fetch pages to show and cite them in AI answers. Blocking one takes you out of that engine's answers.
OAI-SearchBot, PerplexityBot, Googlebot, Bingbot
User-triggered bots
Fetch a page when a person asks about it. Vendors say robots.txt may not apply, since a person asked.
ChatGPT-User, Perplexity-User
Training and dataset bots
Collect pages for model training and open datasets. Blocking them keeps you out of future training and leaves AI search alone.
GPTBot, ClaudeBot, CCBot, Bytespider
Each job has its own token, so you can keep training bots out and still let search bots in.
The AI bots, one by one
OAI-SearchBot
OpenAI · Search
Crawls pages so they can appear and be cited in ChatGPT search. Block it and your pages drop out of ChatGPT's search answers.
Source: OpenAI's bot documentation
PerplexityBot
Perplexity · Search
Crawls pages to show and link them in Perplexity answers. Perplexity says it does not use it to train foundation models.
Source: Perplexity's bot documentation
Googlebot
Google · Search
Google's main crawler. It feeds Search, AI Overviews and AI Mode, so blocking it removes you from all three. This checker does not test Googlebot: Search Console shows how it reads your site.
Source: Google's crawler documentation
Bingbot
Microsoft · Search
Bing's crawler. Its index feeds Bing and Microsoft Copilot answers. Sites often verify it by IP address, so a refusal from our test fetch is not proof that the real Bingbot is blocked.
ChatGPT-User
OpenAI · User-triggered
Fetches a page when a ChatGPT user's request needs it. OpenAI says robots.txt rules may not apply to these visits.
Source: OpenAI's bot documentation
Perplexity-User
Perplexity · User-triggered
Fetches a page when a Perplexity user asks about it. Perplexity says it generally ignores robots.txt, since a person asked.
Source: Perplexity's bot documentation
GPTBot
OpenAI · Training
Crawls pages that may be used to train OpenAI's models. Disallowing it opts your content out of training and leaves ChatGPT search alone.
Source: OpenAI's bot documentation
ClaudeBot
Anthropic · Training
Anthropic's web crawler. It collects public pages that may be used for model training, and it follows robots.txt.
CCBot
Common Crawl · Training
Builds Common Crawl's free web archive, which many AI training sets draw on. It follows robots.txt.
Source: Common Crawl's CCBot page
Bytespider
ByteDance · Training
ByteDance's crawler, used to gather data for its AI models. ByteDance publishes no page for it, so to keep it out a firewall rule is more reliable than robots.txt alone.
Google-Extended
Google · Control token
A robots.txt token read by Googlebot. It controls use of your content for Gemini training and has no effect on Search or AI Overviews. It has no crawler of its own, so the checker reads robots.txt only.
Source: Google's crawler documentation
Applebot-Extended
Apple · Control token
A robots.txt token. It controls whether Applebot's crawl may train Apple's models; Applebot does the crawling. The checker reads robots.txt only.
Source: Apple's Applebot documentation
When robots.txt allows a bot and the fetch fails
A 403, a 429, a dropped connection or a challenge page means something in front of your server turned the bot away: a CDN bot rule, a firewall, a rate limit or a host filter. robots.txt cannot override any of these.
- Open your firewall or CDN security events and filter by the bot's user agent.
- Find the rule that fired. On Cloudflare, check the bot and AI crawler settings as well as custom rules.
- Allow verified bots for that rule, or skip the rule for the bot you want.
- Run the checker again to confirm.
Robots.txt rules for AI bots
Pick what you want and copy the rules. The checker above builds the same rules from your own robots.txt, with only the groups your site is missing.
# AI crawler rules from tryfiremark.com/tools/gptbot-checker

# AI search: allowed
User-agent: OAI-SearchBot
User-agent: Claude-SearchBot
User-agent: PerplexityBot
User-agent: Bingbot
User-agent: Applebot
User-agent: meta-webindexer
User-agent: YouBot
User-agent: Amzn-SearchBot
User-agent: MistralAI-Index
User-agent: Diffbot
User-agent: Webzio
User-agent: Omgilibot
User-agent: YandexAdditionalBot
User-agent: PetalBot
User-agent: Timpibot
Allow: /

# User-triggered: allowed
User-agent: ChatGPT-User
User-agent: Claude-User
User-agent: Perplexity-User
User-agent: DuckAssistBot
User-agent: Google-Agent
User-agent: Google-GeminiNotebook
User-agent: OAI-AdsBot
User-agent: meta-externalfetcher
User-agent: Amzn-User
User-agent: MistralAI-User
User-agent: Diffbot-User
User-agent: Claude-Web
User-agent: cohere-ai
Allow: /

# Training: blocked
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: CCBot
User-agent: meta-externalagent
User-agent: Amazonbot
User-agent: Google-Extended
User-agent: Applebot-Extended
User-agent: Google-CloudVertexBot
User-agent: MistralAI-Training
User-agent: Webzio-extended
User-agent: ImagesiftBot
User-agent: Bytespider
User-agent: anthropic-ai
Disallow: /
Paste these groups into your-domain.com/robots.txt and keep your rules for other bots. A group that names a bot replaces your * rules for that bot, so copy any paths you want closed into these groups too. OpenAI and Perplexity say a change can take up to 24 hours to apply.
After the check
Access is step one. Being named is the goal.
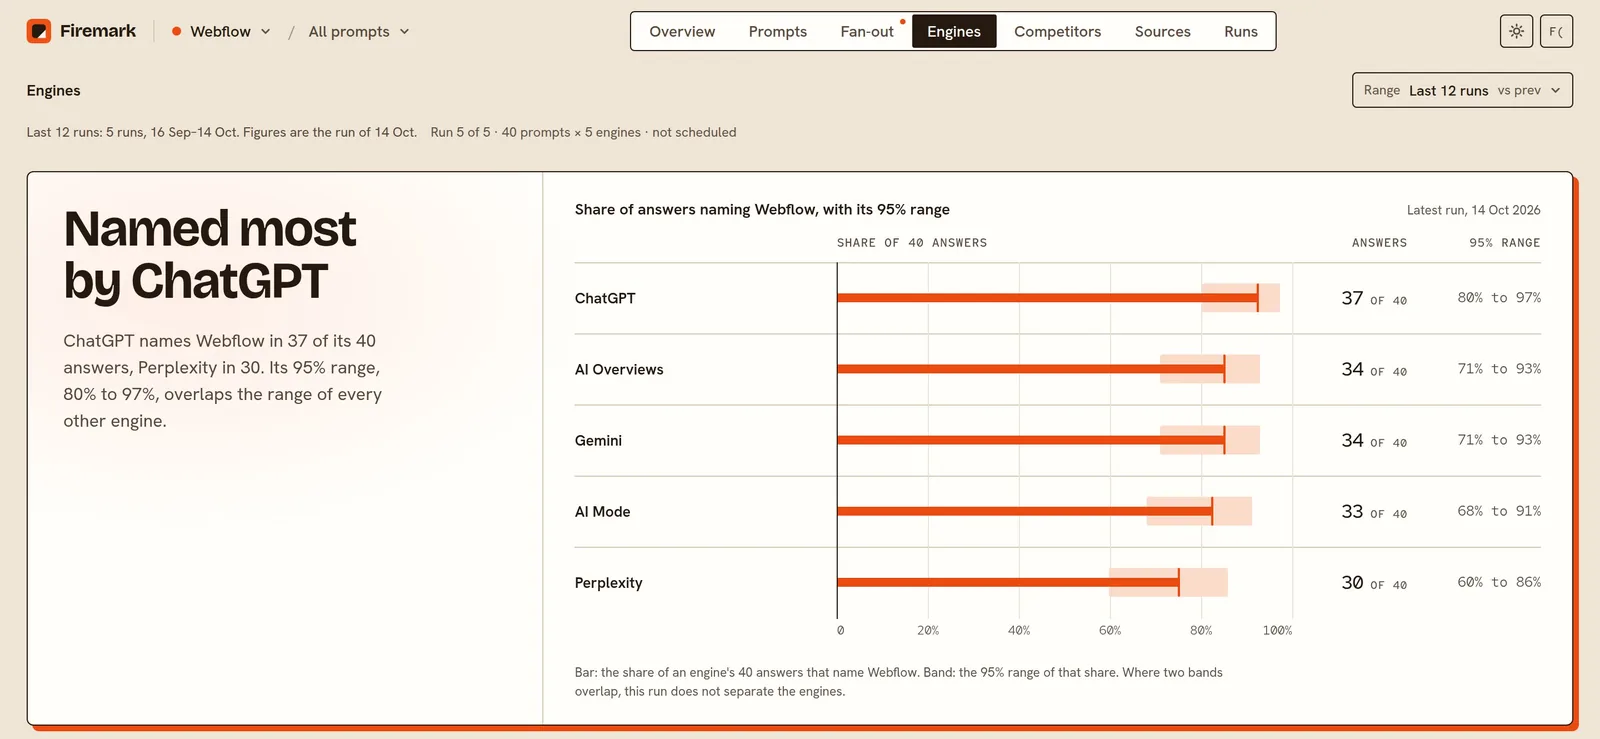
Once AI bots can read you, the question is what the answers say. Firemark asks ChatGPT, Perplexity, Gemini, AI Overviews and AI Mode your buyers' questions on a schedule and counts how often each one names you.
- 25 to 500 prompts, depending on plan
- Up to five engines: ChatGPT, Perplexity, Gemini, AI Overviews and AI Mode
- Daily, weekly or monthly runs against 1 to 10 competitors
- Every answer kept for 13 months
GPTBot checker FAQ
What is GPTBot?
GPTBot is OpenAI's web crawler for model training. Its user-agent token is GPTBot, and a robots.txt group that names it controls it.
Does blocking GPTBot remove my site from ChatGPT search?
No. ChatGPT search uses OAI-SearchBot, which has its own robots.txt group. You can disallow GPTBot and allow OAI-SearchBot.
Why does robots.txt say allowed when the fetch fails?
robots.txt is a request to bots. Your firewall, CDN or host decides what reaches the server, and it can turn away a bot that robots.txt allows.
How do I let AI bots through Cloudflare?
Open your security events, filter by the bot's user agent and find the rule that blocked it. Allow verified bots for that rule, or skip it for the bot you want. Then run the checker again.
Is Google-Extended a crawler?
No. It is a robots.txt token that Googlebot reads. It controls use of your content for Gemini training and has no effect on Search.
How long do robots.txt changes take to apply?
OpenAI and Perplexity both say up to about 24 hours.
Should I block AI training bots?
It is a business choice. Blocking training bots keeps your pages out of future training sets and leaves AI search untouched. The checker reports these bots and never marks a block as an error.
Related free tools
Find out if AI recommends you
Start tracking your brand. New accounts get one free run.