Method · last reviewed
How accurate is AI visibility tracking?
Firemark reports the answers it collected, counted as measured. Every answer is scored, uncertain cases are checked again, and fixed rules decide what we are willing to show.
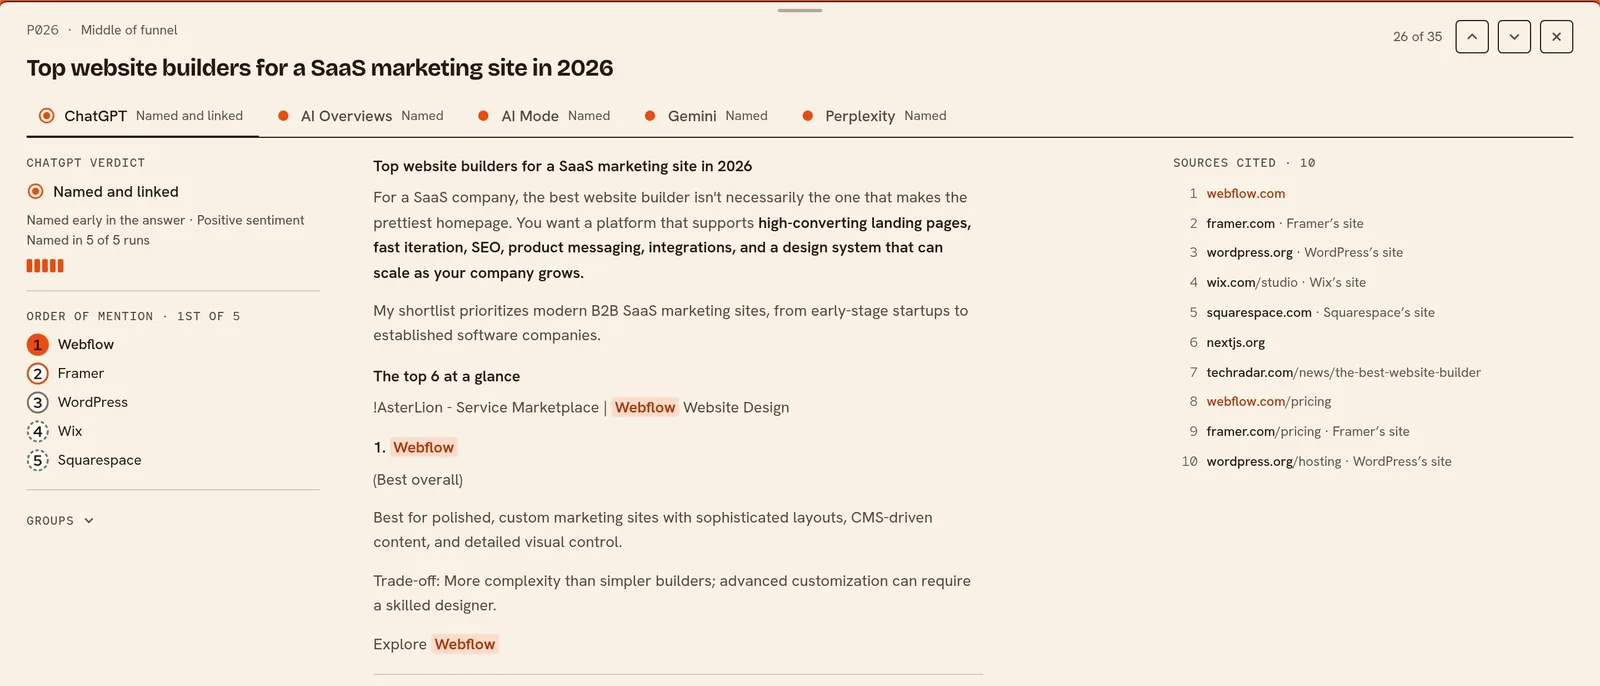
Real Firemark report · example brand Webflow
The rules that decide what Firemark shows
20+
answers before a share is shown. Below that base, you get the count only.
<10
answers and a competitor gets no rank. It shows as "fewer than 10" for that run.
3 + 5
three comparable runs and 5 points or more before a movement is called.
95%
range drawn on each engine's own base, so you see how far a share could move from the sample alone.
2nd
review for names the model cannot settle. A name still undecided counts as not named.
One run
How an AI visibility run works, from start to finish
A run asks every prompt in your basket on every engine in your plan, scores each answer and publishes the results. Answers per run are prompts x engines, so 100 prompts on 4 engines is up to 400 answers.
Your basket of prompts, each with a funnel stage, is the fixed set of questions.
Before the run, we check that each engine is answering. An engine that is not is shown as short.
Each prompt is asked on each engine from the market you track: a US location in English by default, or a French- or Spanish-speaking country on request.
Every answer is scored for who it names, who it links and where.
The run is published, and counts, ranks and claims are worked out from it.
The engines we ask
- ChatGPT (web)
- Perplexity
- Google AI Overviews
- Google AI Mode
- Gemini
Each one asked from a US location in English by default. French- and Spanish-speaking countries on request.
The schedule
Your first run starts as soon as you confirm your basket, and most brands see first results within about an hour. After that you choose daily, weekly or monthly, up to your plan's fastest cadence, and scheduled runs start overnight, US Eastern time.
If an engine does not answer enough of your prompts, we retry before the run is published as short. A failed answer is never counted as your brand being absent.
Each answer
What we record for each AI answer
Whether your brand is named, whether the answer links to you, which funnel stage the prompt belongs to and which sites the answer cites. Named and linked are counted separately.
Named
Your brand's name or one of its aliases appears in the text of the answer. A name found only inside a list of sources does not count.
Linked
The answer links to your website, or to a page from a profile or listing you add. A link alone never counts as named.
The two give four verdicts
- Named and linked
- Named
- Linked but not named
- Absent
- Funnel stage
- Every prompt is tagged top, middle or bottom of the funnel, so you can see where in the buying journey an engine names you.
- Sources
- The sites an answer cites. We count the answers that cite a site at least once, split by answers where you are named and answers where a competitor is named and you are not.
- Position and sentiment
- Which third of the answer holds your first mention, and whether the mention reads positive, neutral or negative. Sentiment is recorded only when you are named.
- Snippet
- The sentence that holds the mention, up to 500 characters. Full answers can be read in the app for 13 months.
- Prompts that name you
- Every screen, CSV export and the MCP can leave out the prompts whose wording names your brand, an alias or your website, with the switch "Leave out prompts that name" your brand.
- Profiles and channels you list
- Add your team's LinkedIn profiles, your LinkedIn company page, YouTube channel and videos, Medium account, and product pages on G2, Capterra, Software Advice, GetApp, Gartner Peer Insights, TrustRadius and Trustpilot. An answer citing one counts as linking to you. A review site's alternatives and comparison pages never count. When the list changes, past runs are counted again. Competitors count as linked through their websites only.
Scoring
How answers are scored
A scoring model decides whether each brand name in an answer is used as the name of that company or product. Checks run in layers.
- Simple checks first
- A model for the rest
- A second review for names it cannot settle
A name still undecided counts as not named. Whether an answer links you, where your first mention falls and the snippet are worked out by code from the answer and its sources. The scorer is a model, so it can be wrong on an edge case, which is why uncertain names get a second look.
The score
How an AI visibility score is calculated
Firemark reports counts instead of one blended score: how many answers name you, how many link your site, and where you rank among the competitors you track.
- Each answer gets a verdict. Your brand is named or not named, and linked or not linked. The two are counted separately.
- Your share is a count over a base. The answers that name you divided by the answers collected, for one engine or for all engines in your plan. A share is shown only when its base is large enough to mean something.
- Movement needs repeat runs. Up or down is reported only after several comparable runs and a change large enough to be more than noise.
What is AI share of voice?
The same count for every brand you track: the answers that name each brand, out of the answers collected. Your rank places you among those brands. A competitor named in very few answers of a run is shown without a rank for that run.
There is no universal good score. The figure depends on your prompts, your market and your competitors, so read your share against theirs and across several runs.
Sample size
How big a sample is, and why AI visibility results vary
Each engine contributes one answer per prompt per run, so for one engine your sample is your prompt count. Across engines it is prompts x engines: up to 75 answers on Lite, 400 on Starter, 1,000 on Growth and 2,500 on Pro.
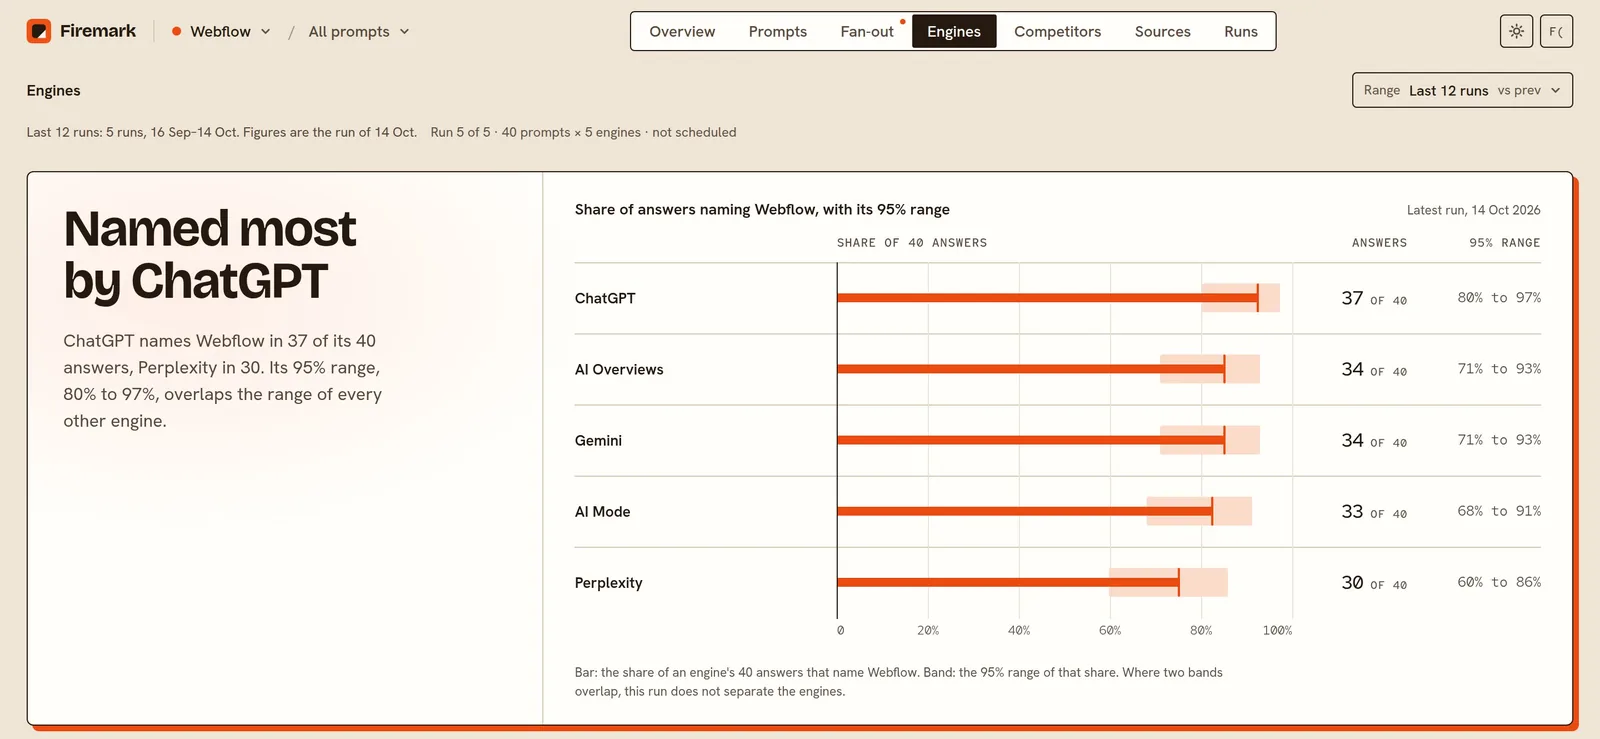
AI engines do not give the same answer to the same question every time, and a small basket moves more than a large one. The Engines screen draws a 95% range on each engine's own base. We do not run a significance test, and we do not put a range around a base that is too small to support one.
| Plan's prompts | Named in | 95% range |
|---|---|---|
| 25 prompts (Lite) | 10 of 25 answers | 23% to 59% |
| 100 prompts (Starter) | 40 of 100 answers | 31% to 50% |
| 200 prompts (Growth) | 80 of 200 answers | 33% to 47% |
| 500 prompts (Pro) | 200 of 500 answers | 36% to 44% |
A range like this covers sampling alone. It does not cover an engine changing how it answers, which is why a change of collection method restarts the comparison.
The limits of this method, and what we do not track
Where and how we ask
- US English by default, with French- and Spanish-speaking countries on request. Each market is asked in its own language, the same way on every run.
- Answers are collected from a logged-out session. A signed-in person with history can get a different answer.
What you get back
- Results are samples of what engines say when asked your prompts. Another phrasing can get another answer.
- Full answers can be read in the app and through the API for 13 months. Through MCP, an assistant reads one full answer per call, on request. Every other MCP tool and the CSV carry snippets of up to 500 characters.
- Counts, verdicts and snippets are kept for the life of your account.
What we do not track
- Countries and languages outside US English and the French- and Spanish-speaking markets we add on request.
- Personalised or logged-in answers.
- Clicks, visits or sales that follow an AI answer. We record what answers say, and what people do next is outside the data.
- Whether what an answer says about you is accurate. We record named, linked, position and sentiment.
Method last reviewed · reviewed whenever the method changes
See which engines each plan tracksSee what Claude and ChatGPT can read through MCPAI visibility accuracy FAQ
How accurate is AI visibility tracking?
Each answer is scored by a model, and uncertain answers are checked a second time. Firemark reports counts as measured, shows a percentage only when the sample is large enough, and reports a movement only after repeated runs. See the limits of the method on this page.
Which countries and languages does it cover?
The United States in English by default. We also track French- and Spanish-speaking countries on request: tell us the markets you need. Each market is asked in its own language, the same way on every run.
What counts as named, and what counts as linked?
Named means the brand's name appears in the text of the answer. Linked means the answer links to your website, or to a page from a profile or listing you add. They are counted separately, so an answer can be named and linked, named only, linked only, or absent. A name that appears only inside a list of sources does not count as named.
Why do results change from one run to the next?
AI engines do not give the same answer to the same question every time, so a run is a sample. We report counts as measured, draw a 95% range per engine on the Engines screen, and call a movement only after three comparable runs and a change of 5 points or more.
Find out if AI recommends you
Start tracking your brand. New accounts get one free run.